Public LLMs in the Workplace: The Growing Risk to Corporate Data and Privacy
Introduction
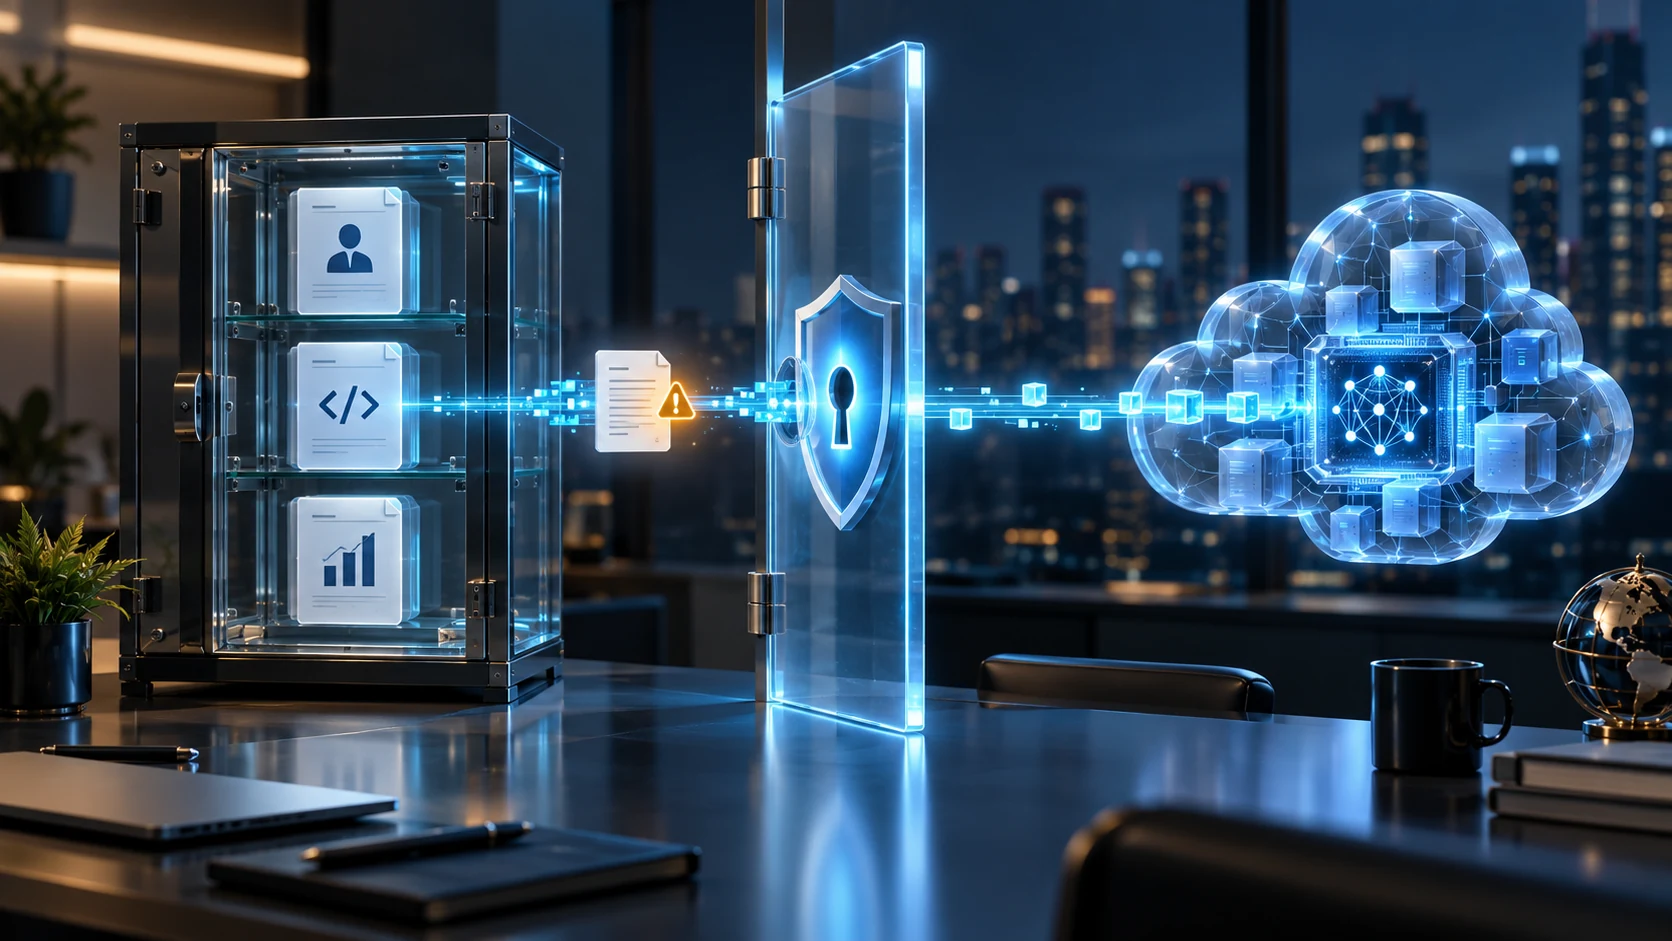
Publicly accessible large language models (LLMs) have become part of everyday working practices. Employees use generative AI to summarise documents, draft emails, analyse information, generate code, troubleshoot technical problems and assist with research. Tasks that previously required substantial manual effort can often be completed more quickly.
However, the ease with which information can be submitted to external AI services introduces an important security and data protection consideration. Internal documents, customer information, source code, financial reports, meeting notes, contracts, security information and authentication credentials can all be included in a prompt or uploaded file.
In this article, “public LLMs” means consumer-facing or otherwise unapproved externally hosted generative-AI services that employees can access directly. It does not mean that submitted information automatically becomes public. Consumer and enterprise products may have materially different contracts, retention settings, administrative controls and commitments concerning model training.
The concern is the expanding range of ways corporate information can reach AI services, rather than a claim that every AI submission causes a breach. Inappropriate use could result in unauthorised disclosure, loss of intellectual property, privacy violations, contractual issues and reputational damage.
The question for organisations is therefore: how can employees benefit from generative AI while the organisation retains appropriate control over the information they provide?
Public LLMs in the workplace: contents
- Workplace use and Shadow AI
- What corporate information could be exposed?
- How information crosses the trust boundary
- Eight data protection and privacy risks
- Agentic AI, prompt injection and excessive agency
- Example: an unapproved client-report upload
- Potential business impact
- Why traditional controls need to evolve
- The role of security assessments
- Defensive measures and data classification
- What to do if information is submitted in error
- Balancing productivity with data protection
- Conclusion and next steps
- References
The growing use of public LLMs in the workplace
Generative AI services have lowered the barrier to accessing sophisticated capabilities. An employee does not necessarily need specialist knowledge or dedicated corporate infrastructure: many services can be accessed through a browser or mobile application within minutes.
Common uses include drafting correspondence, translating documents, analysing spreadsheets, preparing presentations, reviewing contracts, producing source code and summarising meeting notes. These activities can provide business value, but employees may begin using services independently of formally approved systems.
This creates Shadow AI: AI tools or capabilities used for business without sufficient organisational visibility, governance or approval. It can include personal AI accounts, browser extensions, coding assistants, meeting bots, embedded SaaS features, API keys, local models and unapproved plugins or Model Context Protocol (MCP) servers. Local models do not necessarily send data to a hosted provider, but still need appropriate governance and access controls.
The behaviour is not necessarily malicious. The NCSC’s Shadow IT guidance explains how employees may turn to unofficial tools when approved processes do not meet their needs. An employee may be trying to work efficiently without recognising the implications of sending information to another organisation.
An organisation can carefully configure an enterprise AI platform while staff continue to use separate personal accounts. Security teams therefore need to understand both the services officially deployed and those employees actually use.
What corporate information could be exposed?
The information submitted to an LLM varies with the employee’s role. Examples include:
- Developers: application source code, API responses, configuration files, error messages and database queries.
- Finance teams: financial reports, invoices, forecasts, customer records and internal spreadsheets.
- Human resources: CVs, employee details, performance reviews, meeting notes and internal correspondence.
- Security and IT teams: logs, IP addresses, security configurations, vulnerability information, incident details and authentication errors.
Information that appears harmless in isolation may reveal considerably more when combined with other records, prompts or files. Internal identifiers and technical details can expose systems or business operations; IP addresses may also be personal data where they relate to an identifiable individual.
OWASP LLM02:2025 Sensitive Information Disclosure covers risks involving personal information, confidential business data, credentials and other protected material in LLM applications. Two issues should be distinguished:
- Input-side disclosure: a user provides protected information without authority or adequate safeguards.
- Output-side disclosure: an AI application reveals sensitive information through generated output, retrieval, insecure access controls or an attack such as prompt injection.
An ordinary authorised prompt is not automatically a vulnerability. The information, purpose, service configuration and controls determine the risk.
How corporate information crosses the trust boundary
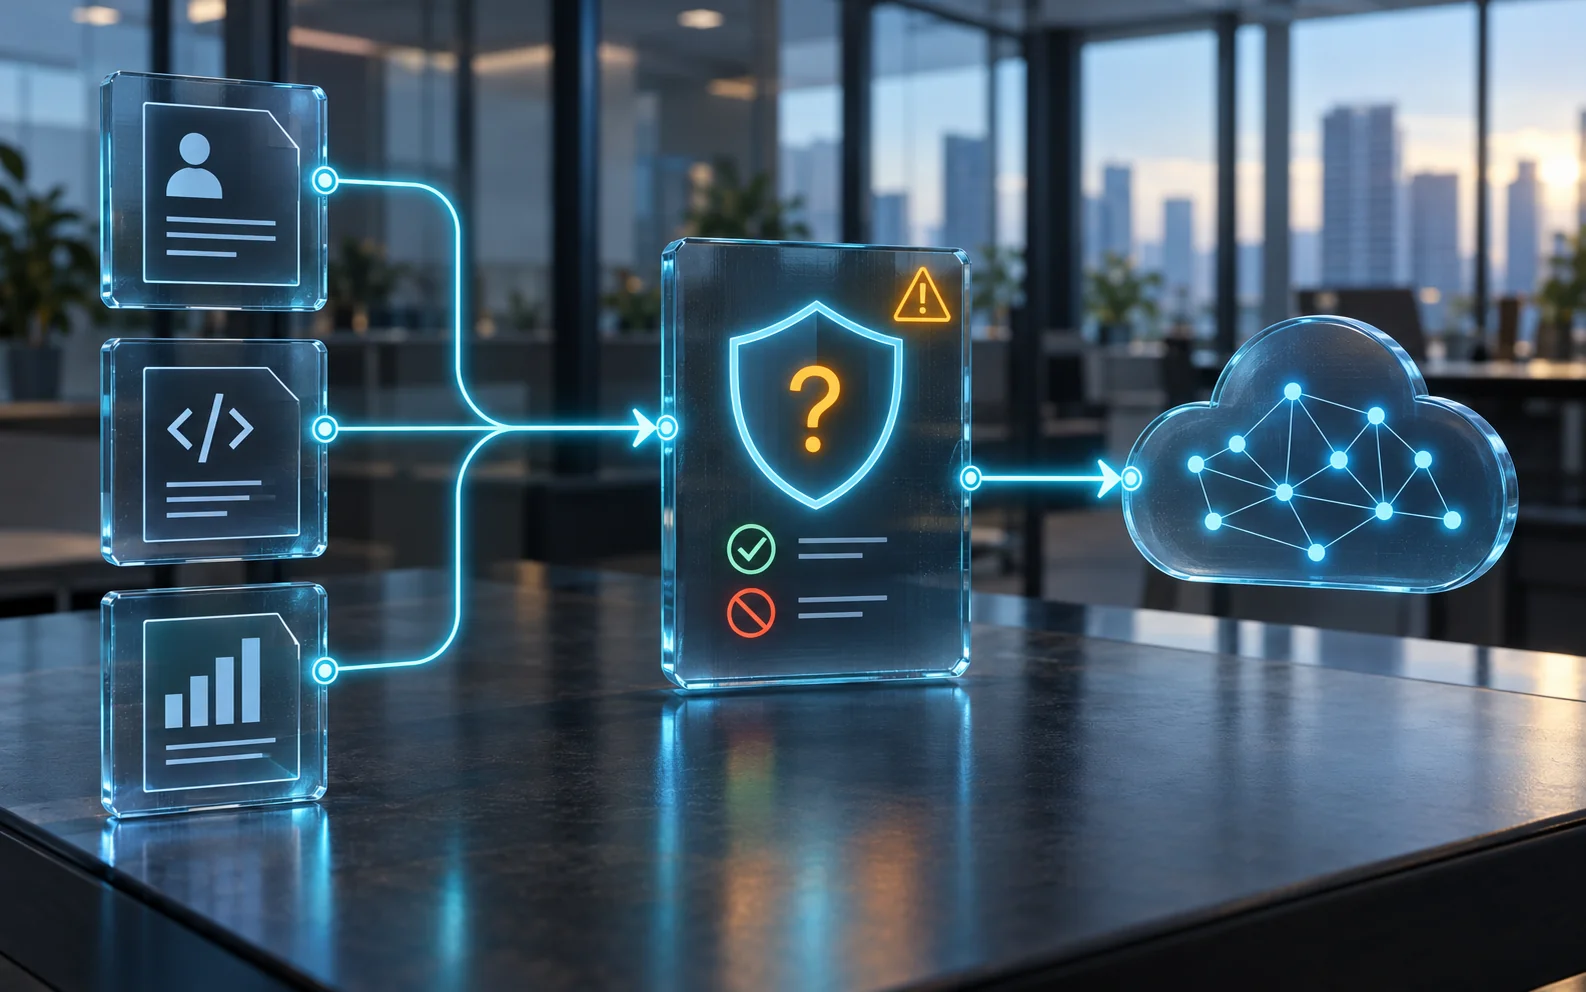
When an employee submits content to a hosted AI service, an external provider processes it using infrastructure outside the organisation’s direct control. No malware or sophisticated attack is necessarily involved: the transfer may occur during an otherwise legitimate business task.
- Corporate informationA document, prompt, log or file is selected.
- User submits contentThe employee sends it to a hosted AI service.
- Trust boundary crossedThe external provider and relevant subprocessors process the content.
- Controls determine the riskAuthority, purpose, contracts, retention and security must be appropriate.
An approved provider may be acting as a contracted processor within the organisation’s authorised processing arrangements. Risk arises when a transfer is unauthorised, incompatible with the data’s classification or purpose, or unsupported by suitable contractual, privacy and security controls.
The security question is not simply whether an employee can access the service. It is whether that employee is authorised to provide that information to that service for that purpose.
Key data protection and privacy risks
1. Sensitive corporate information disclosure
An employee might ask an AI service to summarise a confidential strategy document into five points for a meeting. The summary may be useful, but the complete source document has been submitted. It may contain commercial plans, customer information or confidential findings that the service was never approved to process.
Employees should check the intended use and data classification before submission. Useful output does not establish that the underlying transfer was appropriate.
2. Personal data and privacy
Names, addresses, contact details, CVs, employee records, performance information and financial records may identify individuals. Where an organisation processes personal data through an AI service, it must comply with applicable data-protection law.
Relevant obligations include establishing controller and processor roles and a lawful basis, providing required transparency, applying purpose limitation and data minimisation, ensuring accuracy and security, governing retention and international transfers, and enabling individuals’ rights. The ICO’s AI and data protection guidance explains how these principles apply.
A data protection impact assessment (DPIA) is required where proposed processing is likely to create a high risk to individuals. This is a contextual assessment, not an automatic requirement for every LLM task. Where the provider is a processor, assess the need for an Article 28-compliant contract and appropriate subprocessor and transfer arrangements. See the ICO’s guidance on AI governance and DPIAs.
3. Intellectual property and confidential information
Corporate information does not need to contain personal data to be sensitive. Proprietary algorithms, product designs, research, pricing strategies, internal processes, merger plans and confidential client information may all require protection.
Submitting these materials to an unapproved service may conflict with internal requirements or contractual commitments. For an organisation whose competitive advantage depends on proprietary knowledge, uncontrolled disclosure could have significant commercial consequences.
4. Source code and technical information
A developer troubleshooting an authentication function may paste code into an assistant without considering the surrounding context. Source code, logs and configuration files can reveal application architecture, endpoints, database structures, internal hostnames, business logic or security mechanisms.
Comments, sample requests and command output may also contain sensitive values. In poorly managed environments, these include credentials, tokens and API keys. Use approved tooling and synthetic troubleshooting examples, supported by repository controls, secret scanning and appropriate content inspection. No scanner can identify every proprietary detail or sensitive value.
5. Credentials and authentication information
Passwords, session cookies, bearer tokens, API keys, private keys, database credentials, connection strings and recovery codes must not be submitted to an unapproved AI service. These values may be hidden within otherwise useful logs or HTTP requests.
- API troubleshootingAn employee investigates a failed request.
- Request copiedThe example still contains a bearer token.
- Secret submittedThe request is sent to an unapproved AI service.
- Incident responseReport, revoke or rotate the token, and review its use.
If exposure occurs, treat the secret as potentially compromised. Do not rely on deleting the chat alone: follow the incident-response steps below.
6. Data retention and secondary processing
Data handling can differ between providers, products, plans, features and configurations. Before approving a service, establish:
- what prompts, outputs, files and metadata it stores, and for how long;
- where processing occurs and which subprocessors or model providers receive data;
- who can access content and for what purposes;
- whether content is used for training or model improvement, and what controls apply;
- what deletion, retention and contractual commitments cover each enabled feature;
- whether personal and enterprise accounts receive different protections.
No training is not the same as no retention. A service may exclude customer content from model training while retaining prompts, outputs, files, safety records or application state. Zero-data-retention arrangements may apply only to eligible accounts, models and features, and may not cover connectors, local transcripts or customer-controlled logs. Verify the exact service and configuration.
Perform a dated, product-specific assessment instead of relying on a provider-wide assumption. The NCSC’s LLM guidance recommends protecting sensitive prompts and understanding provider terms. Product capabilities and terms have changed since that guidance was first published, so check current documentation before approving use.
7. File uploads
Uploading complete documents makes AI services more useful, but increases the volume of information transferred. An employee seeking a one-page summary may provide an entire 80-page report, including appendices, hidden spreadsheet sheets or unnecessary personal details.
Data minimisation remains relevant: provide only what is necessary for the task. The ICO’s security and data minimisation guidance addresses limiting personal data and protecting it throughout processing. A small synthetic example may solve a technical problem without exposing a real dataset.
8. AI integrations and connected services
Risk extends beyond manually pasted prompts. Connectors may give an assistant access to email, cloud storage, document repositories, collaboration systems, source code and corporate applications.
Assess the actual access scope, account identity, OAuth permissions, token storage, onward data flows and logging. A read-only connector can still disclose information; a connector with write or execution permissions can also change systems. Review which users can enable integrations and whether the service can route work to other models or providers.
Agentic AI, prompt injection and excessive agency
Some assistants can retrieve documents, browse websites, call APIs, execute code and modify external systems. The security boundary therefore includes the model, orchestration layer, memory, files, browser, tools, credentials and approval controls.
Indirect prompt injection occurs when content obtained from a website, message, file or repository influences an AI system to follow unintended instructions. OWASP’s prompt-injection guidance describes how this can lead to disclosure or unauthorised actions. The impact depends heavily on the data and tools available to the agent.
For example, an assistant reviewing an external document could encounter embedded instructions to retrieve unrelated internal files or contact an external destination. Approval to read a document is not approval to follow instructions found inside it.
OWASP’s Excessive Agency guidance highlights excessive functionality, permissions and autonomy. Limit available tools, use read-only access where possible, enforce authorisation in downstream systems and require meaningful human approval for consequential send, write, delete, execute or financial actions.
The NCSC warns that prompt injection differs from conventional injection vulnerabilities. Instructions and filtering alone cannot be assumed to eliminate the risk. Treat external content as untrusted, constrain what the system can do, and test both prevention and containment.
Example: an unapproved client-report upload
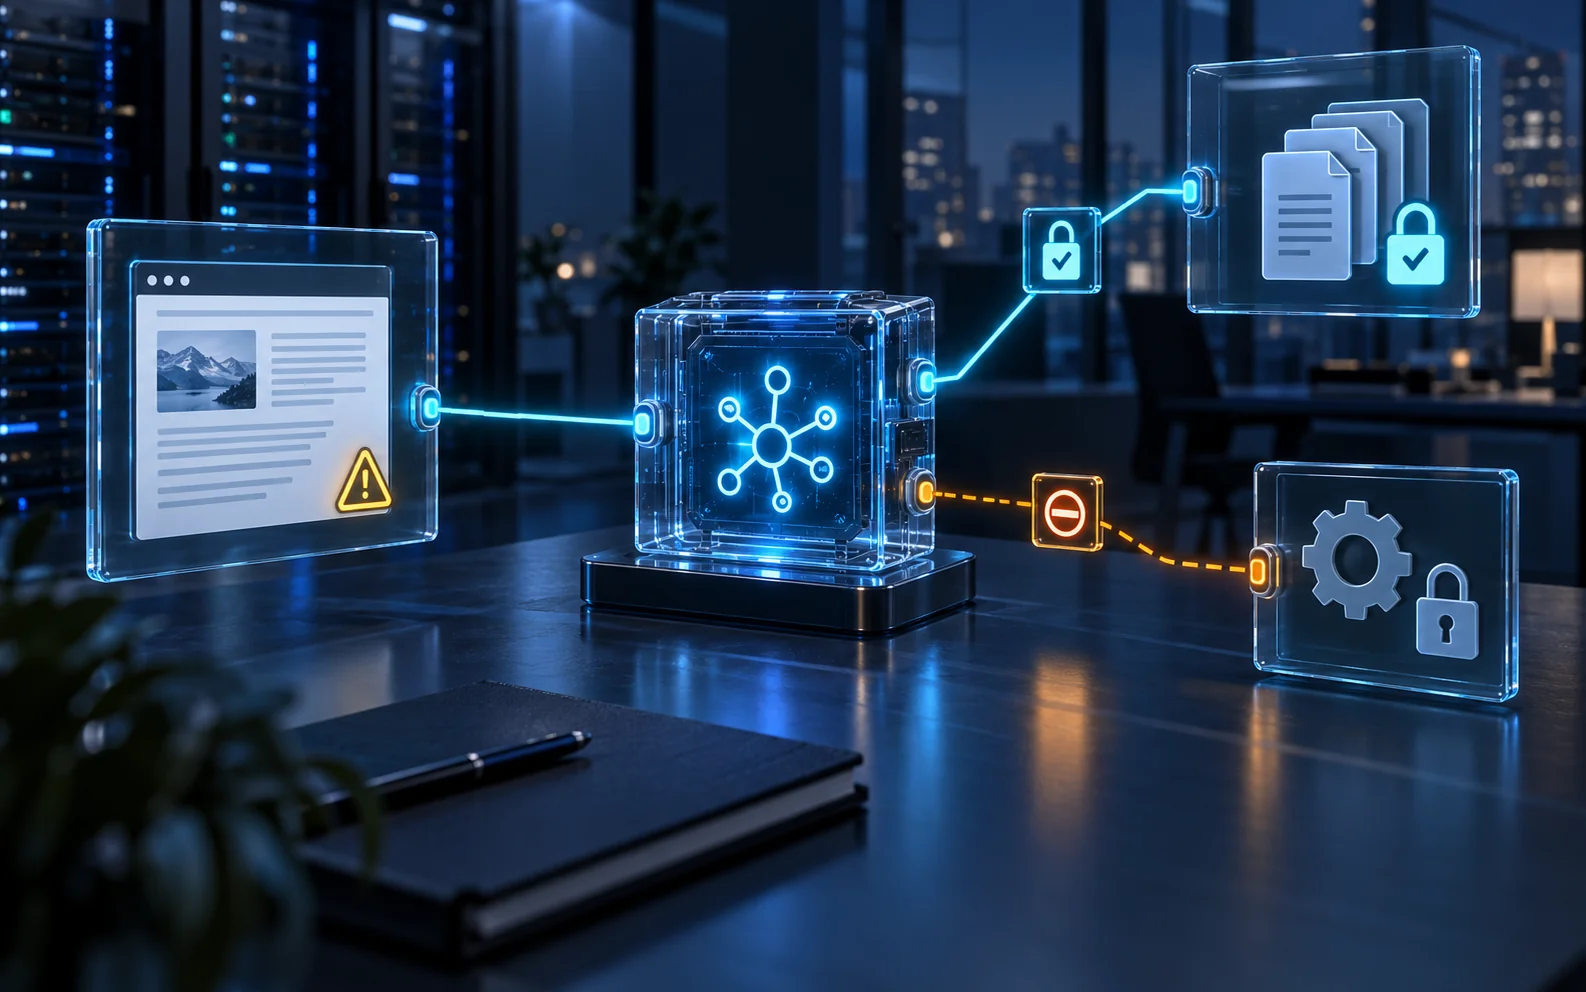
Consider a consultancy employee preparing a client presentation. They receive a confidential report containing customer information and commercially sensitive findings, upload it to a personal AI account and request five executive slides.
The output may be excellent. From the employee’s perspective, the task has been completed efficiently. However, the organisation has not approved that account or service for the report.
- Confidential client reportThe document carries privacy and contractual obligations.
- Personal account uploadThe chosen service is not approved for this information.
- External processingThe provider receives the report, not just the requested summary.
- Potential exposureAssess authorisation, retention, confidentiality and privacy implications.
The employee may not have intended harm, but good intent does not establish permission or suitable safeguards. The organisation needs to determine what was submitted, what terms applied and whether its obligations were met.
Potential business impact
The consequences depend on the information and circumstances. They could include disclosure of confidential material, loss of intellectual property, customer or employee privacy harm, contractual breaches, investigation costs, financial loss and reduced confidence in the organisation.
Customers and partners can be affected even when they had no involvement in the decision to use the AI service. More uncontrolled submissions, limited visibility and weak governance can increase opportunities for exposure; they do not mean that every interaction causes all these outcomes.
Regulatory reporting is also contextual. An organisation must assess an incident rather than assuming that every external transfer is a notifiable breach.
Why traditional data security controls need to evolve
An employee connecting to a legitimate AI service over HTTPS may not generate a conventional malware alert. Encryption protects data in transit; it does not establish that the destination is authorised to process the information inside the connection.
URL blocking alone is incomplete because AI capabilities can be embedded in approved browsers, development tools, productivity suites and other SaaS products. However, modern endpoint data loss prevention (DLP), browser controls, cloud access security brokers and inline content inspection may identify or block some sensitive transfers.
A layered approach combines technical controls with data classification, usable approved services, employee awareness and governance. The NCSC’s guidance on reducing data exfiltration by malicious insiders is relevant to prevention, monitoring and audit controls, although it is not specifically guidance on accidental LLM disclosure.
The role of security assessments
Security assessments can test how AI services interact with corporate controls and realistic employee workflows. A useful scope may include:
- approved and unapproved services, embedded AI features and separation of personal and corporate accounts;
- data-flow, subprocessor and model-provider routing, including changes introduced by orchestration;
- DLP detection of sensitive information and accidental credential submissions;
- connector scope, OAuth tokens, agent functionality, permissions and autonomy;
- direct and indirect prompt injection, retrieval permissions and cross-user access controls;
- memory, conversation history, files, caches, logs and deletion behaviour;
- approval controls for messages, writes, deletions, code execution and financial actions;
- outbound paths through tool calls, browser navigation, rendered links and remote images;
- logging, policy enforcement and incident-response exercises.
Use authorised test environments and synthetic data wherever possible. Assessments should consider employee behaviour as well as technical configuration: a secure deployment can still be misused if staff do not know which information they may provide.
The ICO’s AI risk toolkit can support the privacy assessment. For systems that incorporate LLMs, retrieval or agents, ProCheckUp’s AI security testing service provides a starting point for discussing an appropriate technical scope.
Defensive measures
Organisations do not necessarily need to prohibit generative AI entirely. The aim is to make appropriate use practical while placing clear limits around sensitive information.
Establish an acceptable AI use policy
Define approved platforms and account types, permitted information, prohibited submissions, suitable business activities and an escalation route when employees are uncertain. Include personal accounts, extensions, coding tools, meeting assistants, connectors and agents.
Use concrete examples. “Do not upload a confidential client report to a personal AI account” is easier to apply than a broad instruction to avoid disclosing confidential information.
Provide approved enterprise AI services
A useful sanctioned service can reduce the incentive to use uncontrolled alternatives. Assess its data handling, retention, security, privacy, contracts, administrative capabilities, identity integration and logging before approval. An enterprise label alone is not sufficient evidence that a service suits every data classification.
Record permitted use cases, features, regions, connectors and account settings. Review changes to those conditions rather than treating initial approval as permanent.
Apply data classification
Employees need to understand which information is public, internal, confidential or highly restricted, and how those classifications affect AI use. The following is an illustrative policy model; each organisation should define its own rules.
| Classification | Illustrative AI-use rule |
|---|---|
| Public | May be suitable for approved AI use, subject to purpose and other obligations. |
| Internal | Use only as permitted by corporate policy and approved service settings. |
| Confidential | Use only explicitly approved platforms and workflows with suitable safeguards. |
| Highly restricted | Do not submit to public or unapproved LLM services; follow designated handling procedures. |
Apply data minimisation and sanitisation
Provide the minimum information needed for the task. Remove irrelevant fields, redact or tokenise identifiers, and use synthetic examples where possible. An employee seeking help with a spreadsheet formula can normally use a small fictional sample rather than an entire customer database.
Use the term “anonymised” carefully. Effective anonymisation requires that individuals are no longer identifiable in the relevant context; masking a name alone may not achieve this. Pseudonymised data remains personal data where it can be attributed to an individual using additional information.
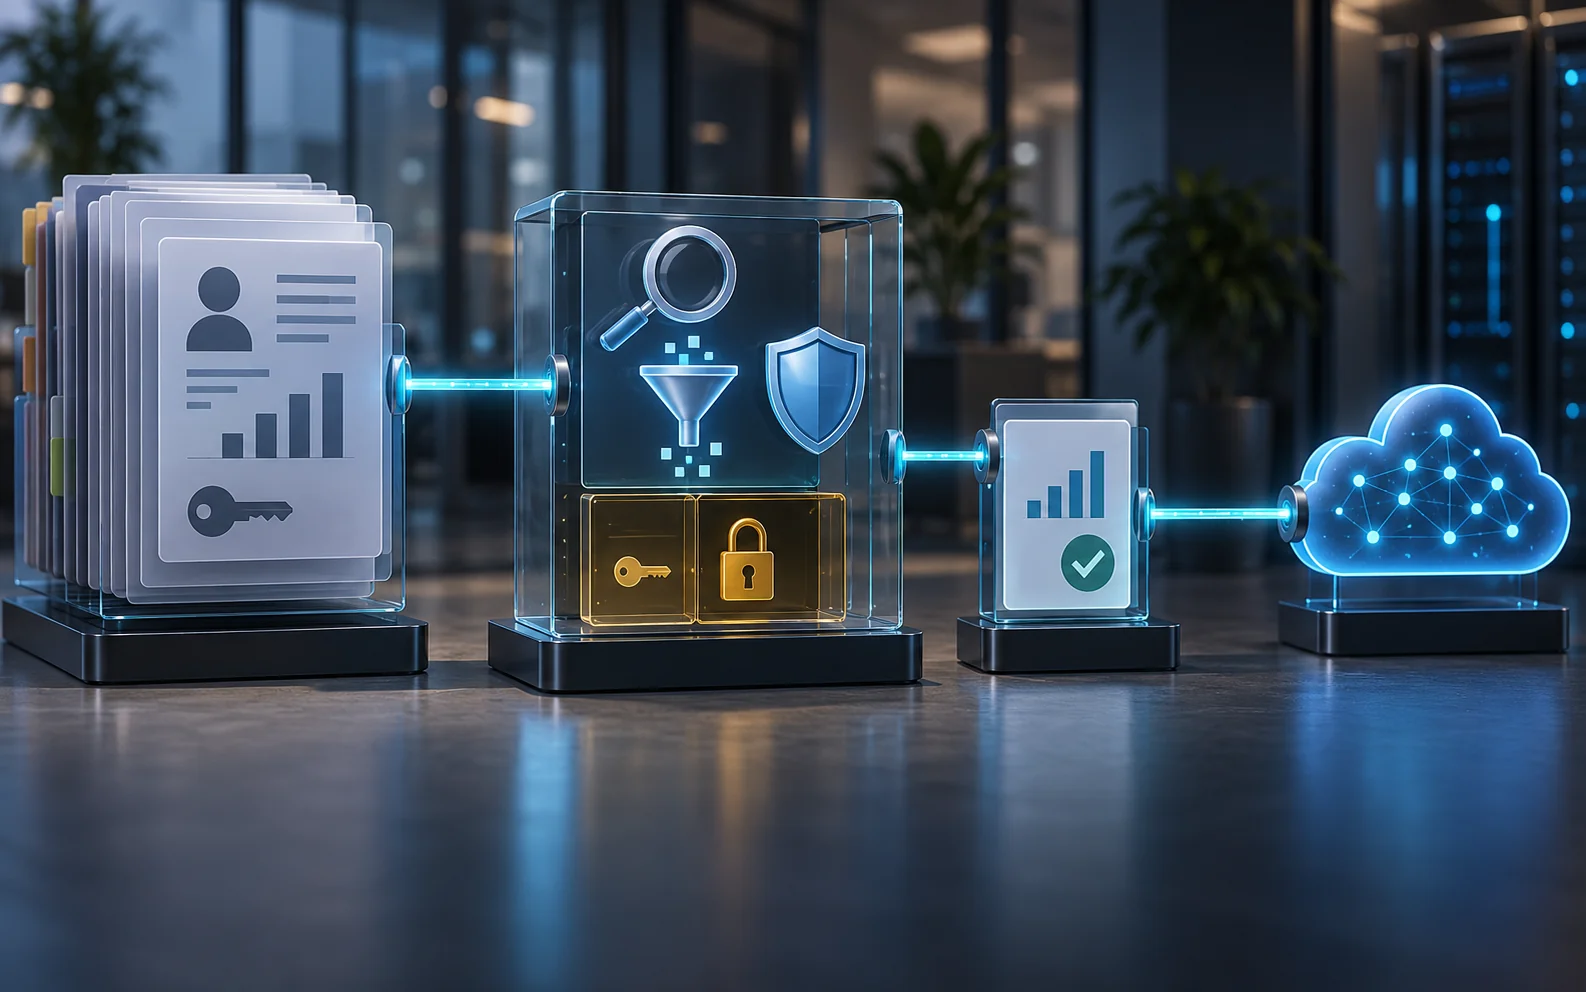
Protect credentials and security information
Use synthetic requests, remove real tokens and review technical examples before sharing. Secret scanning and repository controls can help, but do not replace human judgement about confidential architecture, incident information or proprietary code.
Technical staff should check HTTP headers, logs, configuration, command output and source code particularly carefully. Establish a clear route for reporting mistakes promptly.
Implement proportionate technical controls
Depending on the environment, combine web filtering, cloud access controls, endpoint DLP, identity-based restrictions, browser management, SaaS monitoring and logging. Test whether policies are actually enforced for uploads, copy-and-paste, personal accounts and embedded assistants.
Protect the monitoring systems themselves. Logs, screenshots and captured prompts may contain the same sensitive information that the controls are intended to protect.
Review integrations and agent permissions
Before connecting an AI service to corporate systems, establish what it can read, change, execute and transmit, which users can enable it, and how its activity is recorded. Apply least privilege and use read-only scopes where they meet the need.
For agents, separate the ability to propose an action from authority to execute it. Enforce access rules in connected systems, constrain outbound destinations and require approval tied to the exact consequential action. Test whether hostile external content can influence these controls.
Provide employee awareness training
Explain that AI submissions should receive the same care as information shared with other external cloud services. Practical examples include:
- Use a fictional customer example to draft an email instead of pasting a full customer record.
- Use the approved corporate workflow for client-report summarisation.
- Remove live bearer tokens and session cookies before asking for troubleshooting help.
- Do not enable access to an entire document store when a specific approved folder is sufficient.
Training should encourage early reporting of mistakes and offer a useful alternative to unsafe workarounds.
Monitor and review AI usage
Review services in use, new features, configurations, integration permissions, incidents and policy effectiveness. Employee monitoring should be transparent, necessary and proportionate, with appropriate access controls and retention.
Where feasible, record destinations, data classifications, policy decisions, tool calls and approvals instead of routinely centralising complete prompt bodies. If content capture is necessary for a defined purpose, minimise and protect it.
NIST AI RMF 1.0 and its Generative AI Profile, NIST AI 600-1, support continuing management of AI risks across the lifecycle. Revisit approval when models, features, connectors, provider terms or business uses change.
What to do if information is submitted in error
- Report promptly. Follow the organisation’s security and data-protection incident process, recording the service, account, time and information involved.
- Contain credential exposure. Revoke or rotate exposed secrets and inspect their use. Do not rely on chat deletion alone.
- Preserve relevant evidence. Retain what is needed for investigation while restricting further access and unnecessary copies.
- Establish the processing facts. Determine retention, sharing, connector activity and available deletion options; involve the provider where appropriate.
- Assess obligations and impact. Review confidentiality commitments, affected people and whether a personal-data breach has occurred. Record decisions and corrective action.
For UK GDPR incidents, notify the ICO without undue delay and, where feasible, within 72 hours of awareness unless the breach is unlikely to create a risk to individuals’ rights and freedoms. Where the risk is high, affected individuals generally also need to be informed without undue delay. Not every incident is reportable, but the assessment should be documented. See the ICO’s personal-data breach guidance.
Balancing AI productivity with data protection
Generative AI can provide meaningful benefits when employees understand the boundary between information suitable for approved AI use and information requiring more restricted handling.
Responsible adoption requires employees, IT and security teams, data-protection specialists, legal and compliance teams, and business leadership to work together. Technical controls cannot prevent every mistake; policy alone cannot enforce every boundary. Usable technology, clear rules, proportionate controls and informed staff are stronger in combination.
Conclusion
The simplicity that makes public LLMs useful also makes it easy to submit corporate information to external services within seconds. The risk depends on what is shared, why it is shared and whether the receiving service and its capabilities have been approved for that use.
Organisations should define acceptable use, provide suitable approved services, classify information, minimise exposure, constrain connectors and agents, monitor proportionately and prepare for incidents. Protecting corporate information now includes understanding where employees send data and how external AI systems process or act on it.
To discuss controls, privacy assessment or technical testing for your organisation’s AI use, contact ProCheckUp. Explore our AI security testing and data protection impact assessment services.
References
Guidance checked on 8 October 2026. Provider terms and regulatory guidance can change. The ICO states that its AI guidance is under review following the Data (Use and Access) Act; it explains regulatory expectations and good practice rather than making every recommendation a separate statutory requirement.
- OWASP — LLM02:2025 Sensitive Information Disclosure
- OWASP — LLM01:2025 Prompt Injection
- OWASP — LLM06:2025 Excessive Agency
- ICO — Guidance on AI and data protection
- ICO — Security and data minimisation in AI
- ICO — Accountability and governance implications of AI
- ICO — AI and data protection risk toolkit
- ICO — Pseudonymisation
- ICO — Personal data breaches: a guide
- NCSC — ChatGPT and large language models: what’s the risk?
- NCSC — Shadow IT guidance
- NCSC — Reducing data exfiltration by malicious insiders
- NCSC — Prompt injection is not SQL injection (it may be worse)
- NIST — AI Risk Management Framework
- NIST — Generative Artificial Intelligence Profile, NIST AI 600-1
Categories