2026 Data Centre Attacks: DR Ratings & User Checklist
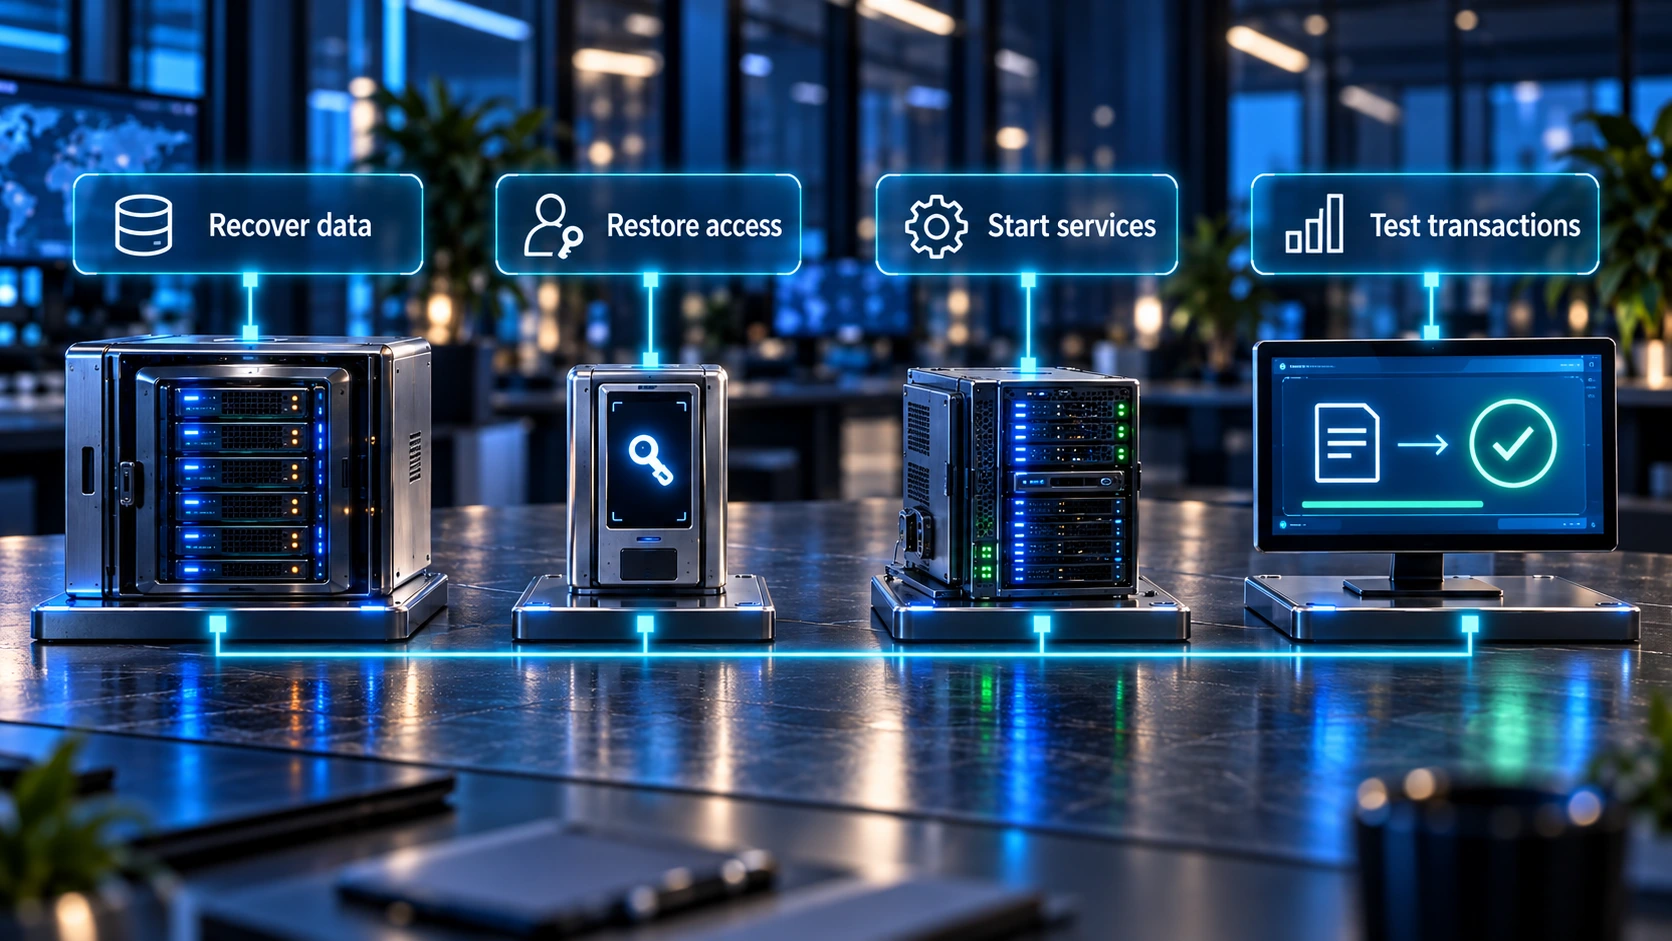
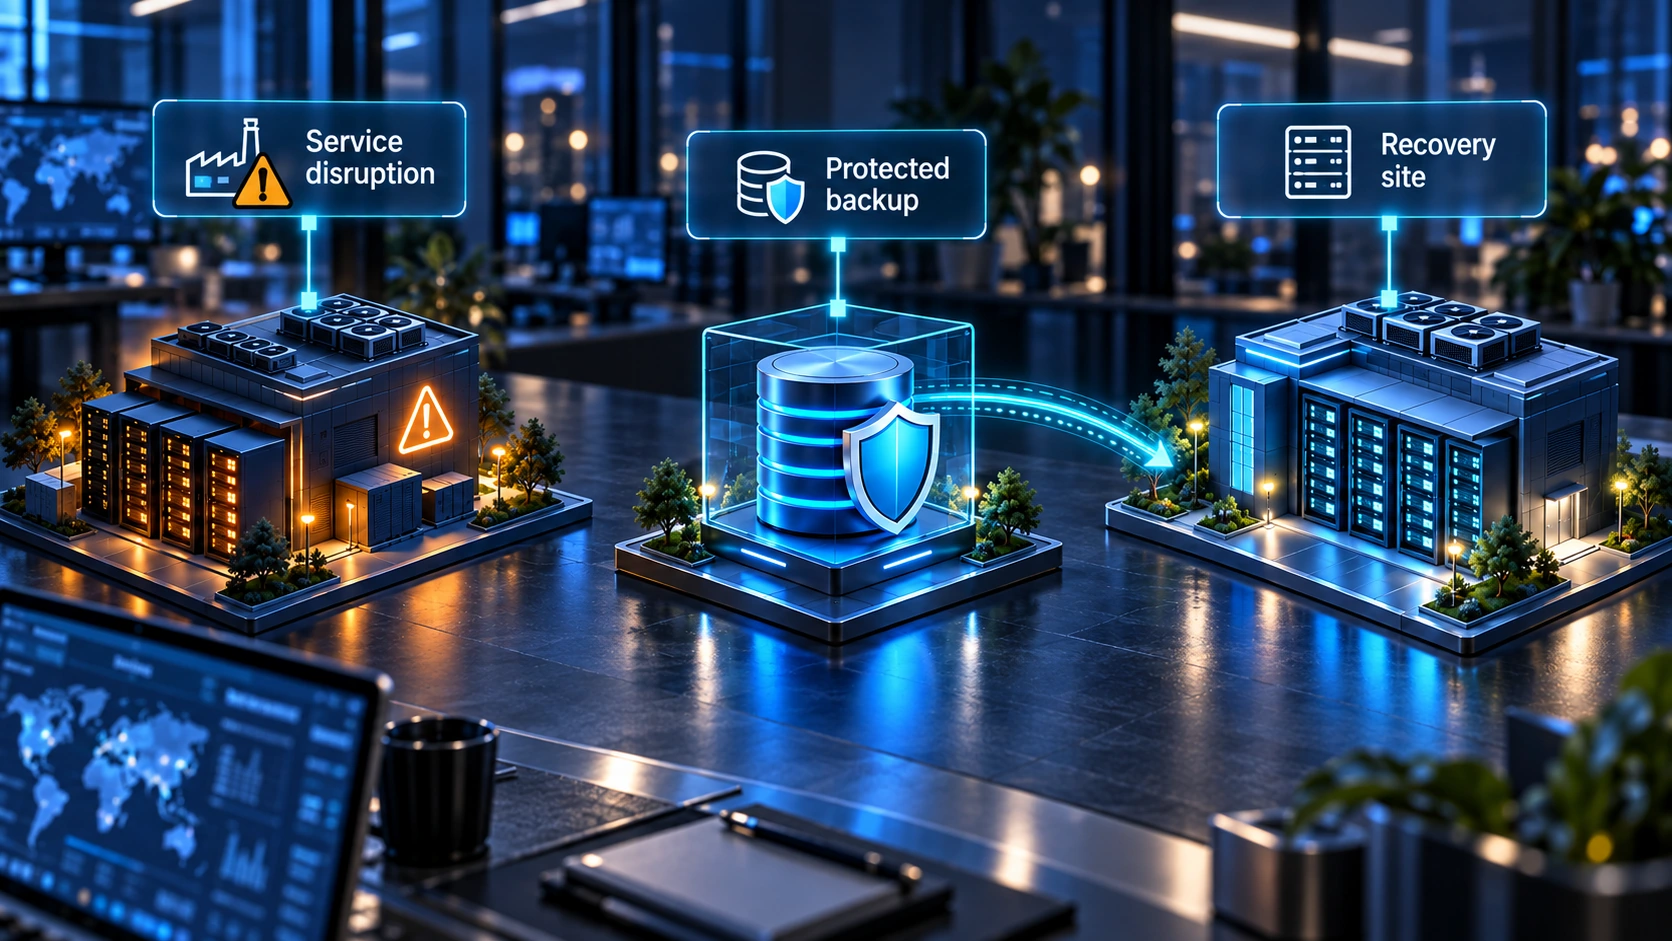 Conceptual illustration of disruption, protected copies and recovery. Select to enlarge; animation can be paused.
When a data centre is attacked, a backup is useful only if you can access it and restore a working service in time. The 2026 incidents below show where disaster recovery (DR) succeeded, stalled or became impossible—and what evidence to request for your own systems.
Research checked: 16 October 2026. Selected incidents from 2026 to date. Provider statements and independent reporting are identified separately; developing recovery outcomes remain provisional.
Cloud services still depend on buildings, power, cooling, networks and people. Check availability, data protection and recovery readiness separately. For immediate action, go to the ten questions to ask your provider and your team.
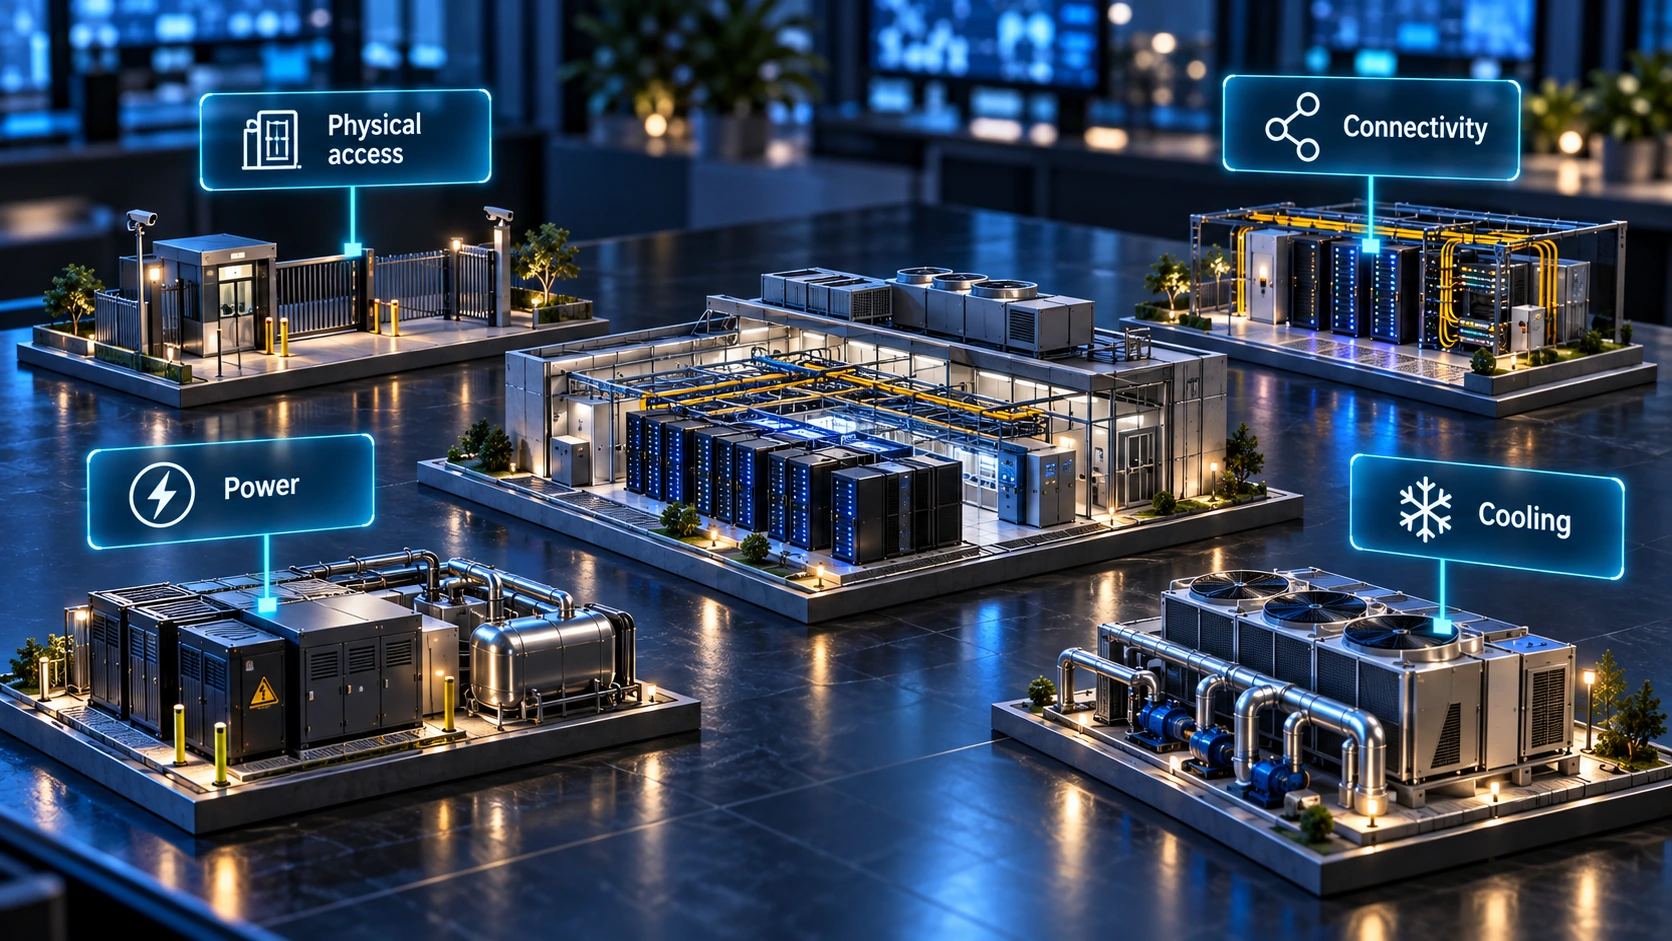
2026 data centre attacks and their impact
Physical attacks and regional disruption
AWS: drone damage and limits to regional recovery
On 2 March, AWS reported direct drone strikes on two UAE facilities and damage from a nearby strike in Bahrain. Damage affected buildings, power and equipment; Bahrain lost a second Availability Zone in April.
On 15 September, AWS said it could not restore access to resources and data hosted exclusively in Bahrain or exclusively in the UAE's mec1-az2 Availability Zone. Work continued on other UAE resources. It said most customers had resumed operations elsewhere using backups or accessible copies. AWS incident updates.
Recovery lesson: assess whether your plan must survive losing an entire region, including recovery copies held there.
Ukraine: recovery depended on the platform and the available copies
September attacks on Kyiv's infrastructure disrupted hosting and connectivity. Reporters Without Borders documented inaccessible news websites and interrupted video services, including effects on Cosmonova customers. RSF reporting.
ITLDC provides a detailed recovery example. Following the 23 September attack, it restored virtual servers from cold-storage backups at other EU sites. By 28 September, it reported its current SSD/NVMe virtual-server platform running elsewhere. Most legacy services had been restored or converted, but some still required help; dedicated-server customers received replacement hardware. IP changes were necessary in some cases. That does not establish recovery of every customer application. ITLDC's dated recovery record.
RealHOST's 28 September update said servers and customer data had been deployed to backup locations, with network optimisation continuing. It also urged customers to hold additional independent copies because communications could remain vulnerable. RealHOST recovery update.
Datagroup's chief executive reported continuity from backup sites after 25 September damage. Attributed CEO statement. Separately, roughly 95% of MiroHost customers were reportedly operating outside Ukraine and unaffected; recovery of the affected minority was not established. Interfax-Ukraine.
Recovery lesson: check the exact platform, backup format and network changes in your plan. A provider can restore one service class while another needs conversion or replacement.
Yandex: recovering traffic did not mean every service had recovered
Yandex confirmed attacks on Sasovo on 7–8 October, Kaluga on 9 October and Vladimir on 11 October. Sasovo and Vladimir stopped operating; Kaluga lost part of its infrastructure. Yandex statement. Cloudflare observed traffic recovering to 85% of normal by 14 October at 18:00 UTC. That measures traffic reaching Cloudflare, not the proportion of customers restored. Cloudflare analysis.
Reported effects included postponed arbitration hearings and inaccessible court files. The Moscow Times, citing Vyorstka. Yandex's guidance, updated 16 October at 17:50 Moscow time, still gave no restoration deadline and warned of restricted resource creation. VM snapshots and Cloud Backup copies could not transfer directly to its BareMetal physical-server service. Yandex recovery guidance.
Recovery lesson: verify backup compatibility and available capacity at the destination. Final data-loss outcomes remained unestablished in the reviewed sources.
Other physical attacks: keep the impact in context
Reported attacks also affected construction projects: attempted sabotage at Pure DC's Amsterdam site in July, with construction reportedly unaffected, and an October drone attack on Sberbank's developing Balakovo site, with banking systems reportedly operating normally. Neither establishes a production failover outcome. The Register; The Moscow Times / Reuters.
Poland's Internal Security Agency confirmed deliberate arson against power equipment at a Starlink ground station on 23 September. Its 16 October statement described an ongoing sabotage investigation and suspected Russian links. This concerns a communications dependency, not a data centre; it does not quantify customer downtime. ABW's official statement.
Ransomware and hosting compromise
Hostinger: containment, patching and a restore from earlier backups
Hostinger reported a LiteSpeed zero-day attack on one Brazilian shared-hosting server on 16 September. It identified malicious scripts (webshells) on 430 accounts and unauthorised commands on ten. The provider said it isolated the server, deployed a vendor fix across its shared-hosting fleet that day, and restored affected websites from pre-attack backups onto a new server. It did not publish a measured recovery time or data-loss window for every website. Hostinger's incident account.
Recovery lesson: combine containment, investigation and patching with a verified restore. Installing a fix alone does not remove changes an attacker already made.
HostDZire: replacement servers could not replace lost data
HostDZire's 5 August notice reported ransomware on all its VMware nodes in India and some in the Netherlands and United States. It said affected data was permanently lost and customers needed external backups; KVM nodes and Leaseweb VPS services were unaffected.
Later updates reported completed replacement VPS provisioning in India and the Netherlands. Its suspected VMware attack route remained unconfirmed. HostDZire incident notice and updates.
Recovery lesson: replacement infrastructure cannot recreate lost information. Establish who protects and can export the data.
Japan: partial recovery at IDC Frontier; rebuilding at CEC
Ransomware disrupted IDCF Cloud from 7 October, affecting 495 organisations in four East Japan Region 1 zones: tesla, henry, pascal and joule. 8 October provider update. By 14 October, IDC Frontier reported extractable snapshot backups for 194 affected customers, with restoration and delivery assessed individually. That did not establish completed recovery for those customers or permanent loss for all others. Other listed zones and regions remained usable. 14 October provider update.
The same update distinguished confidentiality from recovery: IDC Frontier found no evidence of customer virtual-server data being queried or taken outside its systems, but confirmed unauthorised queries of 48 organisations' portal registration records. It found no evidence those records were taken outside either. These are the provider's investigation findings, not an independent assurance of no compromise. IDC Frontier's investigation findings.
CEC's final report on 3 September described a separate ransomware incident in an area apart from the customer systems and data it hosted. It reported temporary service interruptions, isolation and rebuilding of the affected area, and continued provision of restored services in a safe environment. Its investigation found no resulting information leakage; that remains the provider's finding. CEC's final report.
Recovery lesson: distinguish extractable data, restored services and verified application operation. They are separate milestones.
Hosting panels and backup software: separate exploitation warnings
April's CVE-2026-41940 affected cPanel & WHM, prompting patching and compromise-detection guidance. Canadian Cyber Centre; cPanel.
Acronis separately confirmed limited, targeted exploitation of CVE-2026-87886 in its Backup plugin for cPanel & WHM. The local privilege-escalation flaw affects Linux builds before 1.9.3.1021. Its advisory also lists affected Plesk and DirectAdmin products, but identifies observed exploitation specifically in cPanel deployments. Acronis advisory and product updates.
These advisories do not establish the cause of the hosting incidents above. They underline why recovery software itself needs patching, restricted privileges and compromise checks.
Management access and service disruption
Brocloud and Hetzner: interrupted access does not establish data loss
Brocloud reported a 2 January distributed denial-of-service (DDoS) attack affecting websites, webmail and its Plesk control panel. Filtering improved access after about 30 minutes, with intermittent problems over the following three days; its 6 January statement closed the incident. Brocloud statement.
Hetzner's 14 October record describes an attack affecting its APIs and console from 12:58 to 14:25 UTC: 87 minutes. It confirms restored reachability, without identifying the attack technique or establishing virtual-machine downtime. Hetzner incident record.
Recovery lesson: rehearse loss of the management portal or API even when workloads remain online.
DR ratings: assess the incident, then assess your workload
These editorial incident-outcome ratings describe affected services as at 16 October. They are not provider rankings, certifications or assessments of your workload. A C grade means the outcome remains unresolved; it is not a prediction of permanent loss.
Read the scope and evidence with each grade. Provider notices are first-hand accounts, not independent verification. Access-only incidents are discussed but not graded as demonstrated DR.
Swipe horizontally within the table to read all columns.
| Affected scope | Rating | Evidence and limit |
|---|---|---|
| AWS: specified Bahrain and UAE resources | D | 15 September: AWS could not restore access to the specified resources and data. Other regions and customer-held copies are outside this finding. Provider notice |
| HostDZire: affected VMware nodes | D | Provider notice: permanent data loss. Replacement VPS provisioning does not reverse that outcome. Incident updates |
| ITLDC: current SSD/NVMe virtual-server platform | B | Provider notice: migrated and running elsewhere by 28 September. This finding excludes legacy services and does not establish every application's recovery time or data gap. Recovery record |
| Hostinger: websites on one affected Brazilian server | B | 17 September: restore from pre-attack backups and migration reported. Per-site recovery timings and data gaps were not published. Provider account |
| CEC: affected data centre service area | B | 3 September: isolation, rebuilding and restored services reported. No customer-specific recovery-time measurements. Final provider report |
| IDC Frontier: four affected zones | CProvisional | Provider notice: partial snapshot progress; final customer recovery remains unresolved. 14 October update |
| Yandex: affected cloud services | CProvisional | Provider guidance: continuing restrictions and no overall restoration deadline on 16 October. Recovery guidance |
| Datagroup: September incident | AProvisional | Attributed CEO statement: continuity reported, without independently verified recovery measurements. Pryamiy report |
Not rated: MiroHost's affected subset lacks sufficient recovery evidence; Hetzner's notice concerns management access; construction-site incidents do not demonstrate production recovery. The claimed Oracle strike in Dubai on 2 April was denied by Dubai's media office. Reuters / The Jerusalem Post.
What these attacks mean for your business
The cases point to three business exposures:
- Interrupted service: customers cannot transact and staff cannot retrieve records. Plan a minimum workable service and customer communications.
- Lost or inaccessible information: rebuilding a server may leave its records missing. Protect a usable copy and reconcile transactions made during the outage.
- Blocked recovery: identity, keys, APIs or spare capacity may fail together. Test recovery without the normal environment.
Recovery cannot undo data theft. The NCSC distinguishes protection against destructive ransomware from protection against theft for extortion. NCSC backup guidance.
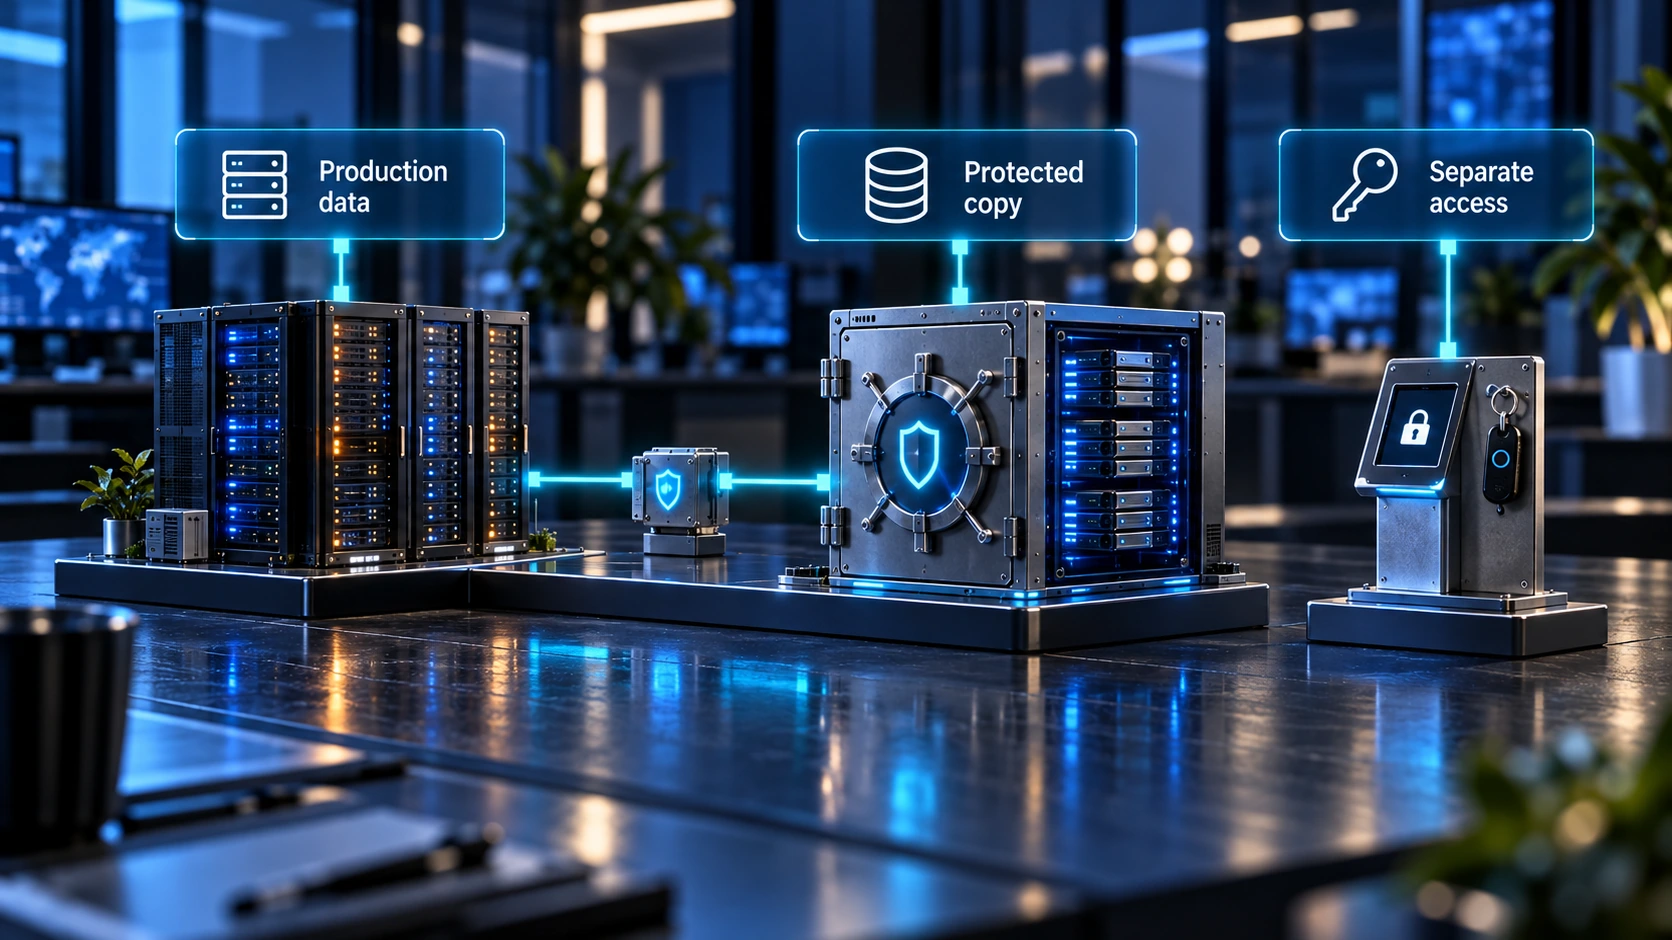
High availability, backups and disaster recovery do different jobs
High availability handles specified component failures. Backups retain recoverable versions of data. Disaster recovery (DR) restores a usable service after serious disruption. Exit planning provides a route away from a supplier.
Replication can propagate corruption as well as legitimate changes. Retain suitable historical recovery points, code and configuration. AWS describes recovery options ranging from backup-and-restore to services active in multiple regions. AWS recovery guidance.
A facility Tier is not an application recovery test. Uptime Institute's Tier classifications concern infrastructure such as power, cooling and maintenance capabilities. Its guidance treats security and regional conditions separately. For procurement, this means checking a facility's certification alongside evidence for your own application's recovery. Uptime Institute's explanation.
Four requirements for a usable recovery
User checklist: ten questions to ask your provider and your team
Request evidence for your actual subscription and configuration, not a general product promise. The NCSC recommends assessing cloud services against your needs and risks. NCSC provider-selection guidance.
Define responsibilities and protect copies
Who is responsible for each part of recovery?
Record who backs up data, protects configurations, restores the platform, rebuilds applications and authorises failover. Include SaaS, managed services, your IT supplier and your own staff.
Ask for: a responsibility matrix with named owners and escalation contacts.
How much downtime and data loss can we tolerate?
Set an RTO for restoring service and an RPO for the acceptable data-loss window. Agree when the recovery clock starts and what counts as working. NIST's contingency planning guide ties recovery requirements to business impact. NIST SP 800-34 Rev. 1.
Ask for: agreed targets, measured end-to-end recovery time and the actual data gap.
Could one event disable both locations?
Check separate communications routes, diverse power, protection of critical plant, staffing and equipment supply, as advised by the NPSA. Include regional hazards, shared administration and data-residency constraints in the location decision. NPSA guidance.
Ask for: a dependency map showing shared power, network, identity and operational failure points.
Can compromised accounts erase the recovery copies?
Include human administrators and automated application identities. Assess offline or protected immutable copies, separate credentials and deletion controls. CISA backup guidance. Check retention changes, key deletion and alerts through a separate channel. NCSC backup principles.
Ask for: permission and retention records, plus an authorised test that a compromised production identity cannot delete the recovery copy, shorten retention or destroy its keys.
Prove the recovery works
Can we recover without the normal login, portal or encryption service?
Exercise emergency access to backups, decryption keys, DNS, certificates and deployment artefacts. The NCSC highlights loss of customer access and destruction of encryption keys as ways to defeat otherwise intact backups. NCSC access and key-management principles.
Ask for: an emergency-access test performed without the normal corporate identity service or email account.
Has a complete service been restored safely?
Check backups for compromise and corruption before use. Validate restored systems and address the intrusion's root cause before production use, then monitor the service and confirm business acceptance. These are explicit recovery checks in NIST's incident-response guidance. NIST SP 800-61 Rev. 3, p. 34.
Ask for: a dated, authorised exercise report covering security checks, login, transactions, integrations and business-owner acceptance.
Can the alternative environment accept and run the recovery?
Check formats, database versions, licences, quotas, IP changes, DNS and partner allowlists. Establish which capacity already exists and which must be provisioned during an outage. A higher quota alone does not prove capacity is available. Measure transfer and restore time, including steps dependent on management APIs. AWS guidance on capacity and management dependencies.
Ask for: a restore at the intended scale, measured transfer time and evidence of available or reserved capacity, including any limits or expiry.
Operate, communicate and improve
Are management systems and automation credentials protected?
Include hypervisors, hosting panels, backup plugins and deployment accounts. Check patch levels, least privilege and secret revocation after exposure. Retain logs outside the affected environment for investigation.
Ask for: current software versions and patching owners, privileged-account inventories and independent log-retention arrangements.
How will we communicate and keep operating?
Keep contact channels independent of corporate email and cloud identity. Plan customer updates and manual workarounds. Verify recovery instructions through a known provider site or established contact: Yandex warns of phishing messages offering restoration, migration or compensation during its outage. Yandex recovery and phishing guidance.
Ask for: offline contacts, decision authority, a tested update schedule and a way to authenticate urgent recovery requests.
Can we leave, and what recovery is included?
Confirm export formats, transfer charges, retention and support priorities. Separate availability commitments from explicit restoration obligations and customer responsibilities. Review certification scope, exclusions and insurance with procurement or legal advisers.
Ask for: a tested export and re-import, a costed exit plan and written recovery commitments for your service.
A practical plan for the next 30 days
Start with critical services that have no independently accessible copy, no tested destination, or one identity able to remove every recovery option. Use exercises to test assumptions and update the playbook. NIST recovery-planning guidance.
- Week 1: identify critical services, business owners, dependencies and acceptable downtime and data loss.
- Week 2: collect provider evidence and identify any service with no independently accessible recovery copy or documented restoration route.
- Week 3: run an authorised recovery exercise in an isolated environment and a tabletop exercise for loss of the primary region or administrator access.
- Week 4: resolve the highest-impact gaps, record actual results, assign remaining actions and schedule the next exercise.
Your own recovery evidence should answer three questions: which failures can we survive, how soon can customers use the service, and how much data could be missing? Test the responsibilities on both sides of the provider agreement.
Sources are linked beside the claims they support. Provider statements, independently observed traffic and attributed news reports are identified separately. The ratings are this article's editorial assessment; NCSC, CISA and NIST have not rated the providers listed here. Recheck developing incidents before relying on the article for a supplier decision.
Categories